
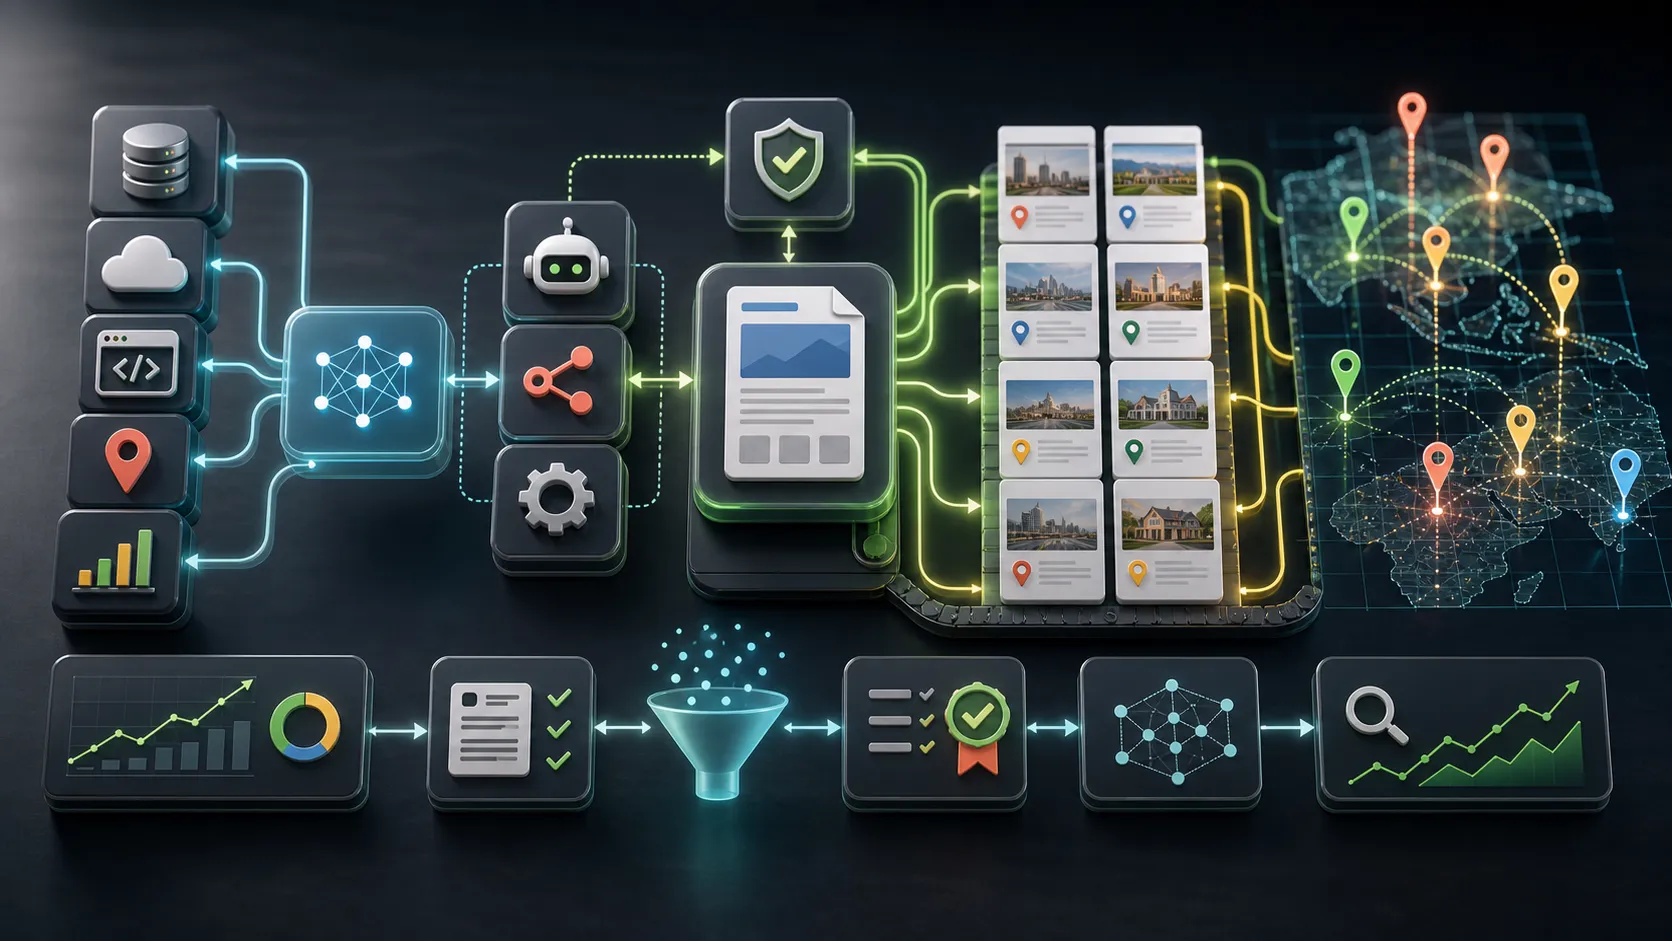
Programmatic SEO has changed. The old model was simple: take one landing page template, swap the service, city, category, or product variable, and publish thousands of near-identical URLs. That approach used to capture long-tail traffic. It is now a liability.
Modern search systems evaluate semantic depth, originality, experience, and usefulness. Google’s AI Overviews, answer engines like Perplexity and ChatGPT, and traditional search crawlers all reward content that can be parsed, trusted, cited, and connected to real data. That means programmatic SEO is no longer mainly a content production problem. It is a data orchestration problem.
Quality at scale now requires a technical architecture: structured data sources, repeatable templates, AI automation workflows, programmatic SEO systems, technical SEO and GEO, internal linking, schema, freshness loops, and human quality control.
This article explains how to build programmatic SEO without thin pages, using AI agents, n8n workflows, Model Context Protocol integrations, localized geospatial data, and crawlable static or server-rendered pages.
Introduction: The Architectural Shift in Search Discovery
Search engine optimization has shifted from heuristic keyword matching toward semantic synthesis driven by Large Language Models. Historically, programmatic SEO involved the mass generation of landing pages by swapping localized keywords or generic string variables inside a static HTML template. While that approach previously captured long-tail organic traffic, contemporary search algorithms and AI-driven answer engines have made low-effort templating obsolete.
Current search quality guidance targets pages where the main content has little effort, little originality, and little added value. In practical terms, a page that only changes the city name, industry label, or product category is not a durable SEO asset. It is a thin-content risk.
Modern discovery engines deploy neural search systems and language models to evaluate semantic depth, firsthand experience, and real-world utility. Google’s AI Overviews and the adoption of answer engines have introduced a newer operational discipline: Generative Engine Optimization, or GEO.
Within this framework, programmatic SEO still works, but the baseline requirements are much higher. Scaling organic visibility now demands unique data pipelines, structured technical architecture, and AI workflows that maintain quality across many generated URLs.
For digital enterprises and service organizations seeking scalable organic growth, the objective is no longer content generation by itself. The objective is data orchestration. Modern strategies synthesize AI automation, unique database integrations, and programmatic execution to produce high-value, intent-driven assets at scale.
The Mechanics of Generative Engine Optimization
To engineer high-quality programmatic pages, architects first need to understand how content is ingested, processed, and cited by modern generative search engines.
Generative Engine Optimization is the technical and editorial discipline of structuring digital assets so AI platforms can discover, ingest, trust, and cite the content when synthesizing responses to complex user queries.
The Transition from Keyword Density to Citation Authority
Traditional search algorithms relied heavily on keyword targeting, internal link authority, and external backlink profiles. Generative answer engines operate more heavily on semantic entity extraction and citation authority.
Generative engines assemble responses through a multi-step pipeline:
- Discover pages through crawlers, structured feeds, sitemaps, or protocols such as IndexNow.
- Parse raw HTML and JSON-LD schema for semantic cues.
- Retrieve isolated text chunks relevant to the prompt.
- Generate a synthesized answer with citations to source material.
That changes the optimization target. Instead of only targeting rigid keyword phrases, programmatic content must map conversational intent and provide extractable factual blocks. Users interact with AI engines through complex, multi-part prompts instead of short keyword fragments.
To become a cited source, programmatic content needs modular clarity. Structured blocks, ordered steps, concise claims, tables, and direct answers make it easier for AI systems to extract the right passage.

| Operational Metric | Traditional Search Engine Optimization | Generative Engine Optimization |
|---|---|---|
| Primary ranking signal | Organic position | Visibility score and citation frequency |
| Primary trust mechanism | Domain rating and external backlinks | Citation authority and entity recognition |
| Standard user input | Fragmented keywords, such as “Miami plumber” | Conversational prompts and complex intent |
| Core success benchmark | Total traffic volume and click-throughs | AI citations, share of voice, and brand mentions |
| Optimal content format | Long-form narratives with keyword placement | Extractable claims, structured blocks, and direct answers |
| Architectural focus | Internal linking and URL hierarchies | Schema markup, API integrations, and llms.txt |
Analyzing AI Overview Selection Criteria and Performance Metrics
Empirical SEO research has suggested that sources cited within Google’s AI Overviews often originate from pages already ranking strongly in traditional organic search. AI Overviews are also triggered dynamically based on query classification. They appear more often for informational intents, complex multifaceted questions, and long-tail semantic queries. They appear less often for some highly commercial or transactional queries.
AI Overviews have also changed user click behavior. Some industry studies have reported lower click-through rates for standard organic listings when an AI Overview is present, while cited sources can receive stronger click attention than uncited competitors.
These figures vary by query type, SERP layout, commercial intent, and industry. The strategic point is more stable than any single benchmark: a programmatic SEO page should not only chase a blue-link ranking. It should function as a structured, authoritative data repository that AI systems can use for claim extraction.
That requires technical precision. The DOM structure, schema, internal links, factual blocks, and database architecture all need to support machine parsing and human usefulness.
The Anatomy of High-Quality Programmatic Architectures
To avoid thin content, programmatic infrastructure must deliver unique value on every generated URL. The solution is to stop spinning text and start enriching data.

Leveraging Proprietary and Unique Data Sources
The foundational layer of quality at scale is proprietary or hyper-specific data. Instead of deploying a template with generic marketing copy and swapped city names, a strong programmatic page becomes an interface for localized data, verified customer reviews, contextual environmental variables, dynamic visual datasets, or internal business intelligence.
Useful sources can include:
- Product catalogs with specifications and availability.
- Local service records from a CRM.
- Verified customer reviews by service and location.
- Municipal open data APIs.
- Geospatial datasets.
- Comparison matrices.
- Partner API data.
- Industry or category taxonomies.
For example, a sophisticated programmatic architecture could aggregate local building codes, calculate average service costs from historical CRM data, generate neighborhood-specific case studies, and integrate weather patterns that create demand for maintenance services.
This data-first approach satisfies the core requirement for unique, non-commodity content. The page is no longer a sentence template. It becomes a useful synthesis of information that is difficult to find elsewhere.
Designing and Implementing the Freshness Loop
Static programmatic pages decay when their underlying data becomes stale. To maintain relevance, the architecture should include a freshness loop.
A freshness loop is an automated cyclical pipeline where external and internal data sources are routinely checked for updates. When the data changes, the resulting facts, calculations, summaries, and page modules are updated without a fully manual rewrite.
A practical workflow can look like this:
- A new project, review, permit, listing, or service record appears in a database.
- The workflow recalculates aggregate local statistics.
- An AI agent summarizes only the provided data.
- The generated content is checked against quality rules.
- The updated Markdown, HTML, database row, or CMS entry is published.
- The sitemap or indexing signal is updated.
This keeps the content current, improves trust, and gives both users and crawlers a reason to revisit the page.
Systematizing Trust Signals and E-E-A-T at Scale
Experience, Expertise, Authoritativeness, and Trustworthiness are critical evaluation pillars for modern search. To scale E-E-A-T across a programmatic deployment, explicit trust signals should be built into the core templates.
Key trust signals include:
- Dynamic authorial attribution: Link programmatic assets to verified subject matter experts and support them with Person and Organization schema.
- Citation transparency: Show visible links to the API endpoints, local government data portals, or internal sources behind numerical claims.
- Review aggregation and verification: Pull hyper-local, service-specific verified reviews to demonstrate real customer experience.
- Clear update dates: Show when the page was reviewed or when the underlying data was refreshed.
- Specific conversion paths: Give users a practical next step instead of leaving them on a passive information page.
Data-Driven Localization: Using Open Data APIs in Florida
For service organizations, real estate teams, and local businesses, civic and geospatial data can enrich programmatic pages with factual local context.
Instead of writing generic city pages, a business can query municipal open data portals and build landing pages that answer specific local questions with evidence.
Integrating the City of Miami and Orlando Open Data Portals
Florida municipalities provide useful public datasets for developers, researchers, and business operators. The City of Miami Developer Portal offers access to civic datasets through REST API strategies, Esri Geoservices, and GeoJSON formats. The City of Orlando Open Data portal provides datasets such as permitting reports, vacant lot inventories, zoning parameters, and public safety data.
For a Florida SEO strategy, this matters because a local page can be built from real local signals instead of thin geographic language. A Miami technical SEO page, for example, can be stronger when it connects local intent, service context, and factual operating conditions.
| Florida Municipal Dataset | Available API Format | Programmatic SEO Application |
|---|---|---|
| Miami 311 Service Requests | Geospatial REST API | Identify hyper-local infrastructure issues and trigger pages for restoration, plumbing, roofing, or disaster recovery services based on incident clusters. |
| Miami Building Permits | GeoJSON or REST | Aggregate commercial permit timelines and construction costs for real estate, construction, and investment guides. |
| Miami 21 Zoning Data | ArcGIS Geoservice | Create localized commercial property guides that update as transect zones or zoning context changes. |
| Orlando Permitting Reports | Socrata Open Data API | Identify emerging development zones and generate B2B service pages for new commercial construction. |
| Orlando Vacant Lots Inventory | REST API | Support pages for developers, landscapers, property maintenance companies, and real estate operators. |
Case Study Architecture: Commercial Real Estate and Construction
Consider a construction firm or commercial real estate consultancy operating in South Florida. The organization can use Miami building permit data, which includes attributes such as application dates, processing status, estimated costs, and review timelines.
An advanced programmatic SEO architecture could query this dataset on a weekly schedule to generate and update neighborhood-specific insights. The resulting pages could include:
- Aggregate data on average timelines for commercial permits in specific Miami transect zones.
- Cross-references to Miami 21 zoning data.
- Interactive maps showing recent development inside a defined radius.
- AI-generated summaries of construction trends based only on raw cost and timeline data from the API.
This creates a stronger page than a generic “commercial real estate Miami” article because it answers a real local question with current data.
Case Study Architecture: Disaster Recovery and Property Maintenance
Service businesses focused on roofing, plumbing, or property restoration can apply the same pattern to Miami 311 service request data.
By filtering geospatial data to specific ZIP codes or coordinates, an automated analysis system can identify neighborhoods with concentrated reports of flooding, downed trees, infrastructure failures, or related issues.
Programmatic landing pages for those neighborhoods can reference empirical local data and offer services that directly address verified community needs. In Central Florida, businesses can use Orlando vacant lot inventory or permitting reports to identify development zones and create useful pages for developers, maintenance teams, and B2B service providers.
This approach produces pages with factual density and local originality. That is the difference between useful local SEO and low-value doorway pages.
Automating the Production Pipeline with n8n and AI Agents
Executing data integration, statistical calculation, and content generation across many URLs requires orchestration infrastructure. n8n is a strong fit for complex, data-driven SEO operations because it supports custom logic, JavaScript, self-hosting, API integrations, and flexible workflow design.
Unlike rigid SaaS automation tools, n8n gives technical teams granular control over workflow logic, error handling, and data custody. That matters when the programmatic SEO system needs to handle proprietary CRM data, local API credentials, search datasets, and publishing credentials.
Designing the Technical Workflow Architecture
A high-quality programmatic SEO pipeline in n8n typically uses multiple AI agents and validation steps in sequence.
- Trigger execution and data acquisition: The workflow starts from a cron schedule or webhook. An HTTP Request node retrieves data from a target API, such as a Miami geoservice endpoint, Google Ads keyword export, Search Console export, or proprietary CRM.
- Agentic data analysis and gap identification: Raw JSON is parsed and passed to an AI model through an integration such as LangChain. The agent is constrained by a strict system prompt and asked to identify intent gaps, competitor patterns, or useful page modules from the provided data.
- Content synthesis and formatting enforcement: A second AI node creates the page content in modular, answer-focused sections with clear H2 and H3 headings. The output should remain visible in plain HTML or Markdown, not buried inside client-only UI.
- Metadata generation and schema implementation: Another node generates title tags, slugs, meta descriptions, and JSON-LD such as FAQPage, Article, Organization, or LocalBusiness schema.
- Quality assurance and human-in-the-loop routing: Before publishing, a validation sub-workflow checks cannibalization, schema presence, source references, required fields, word count, duplication, and hallucination risk. Higher-risk drafts are routed to a human reviewer in Slack, Teams, or a CMS queue.
- Publication and algorithmic indexing: Once validated, the workflow publishes to a CMS, static site repository, or database. It can also update the XML sitemap or submit an indexing signal.
| n8n Core Node Category | Primary Function in Programmatic SEO |
|---|---|
| Webhook and Cron nodes | Initiate the freshness loop based on time intervals, database changes, or external events. |
| HTTP Request nodes | Fetch raw geospatial data from Florida open data APIs or external SEO tools. |
| LangChain and AI Agent nodes | Process data, perform SERP gap analysis, and synthesize modular HTML or Markdown content. |
| PostgreSQL and Supabase nodes | Query the internal database to prevent keyword cannibalization and log published URLs. |
| Communication nodes | Route generated assets to human editors for final quality assurance and approval. |
This infrastructure lowers the manual overhead of large content operations and helps capture long-tail search intent without relying on a traditional high-volume content team. For teams that need help connecting secure automation, API keys, and error handling, AI workflow automation becomes part of the SEO architecture rather than a separate operational tool.
Mitigating the Drawbacks of Automation Platforms
Automation platforms and AI agents create leverage, but they also introduce operational risk. Community nodes can break after platform updates. Large analysis jobs can exceed model context windows. Vague prompts can produce generic advice instead of useful output.
The system should never rely on the language model to invent facts from its training data. Use the model as a reasoning, categorization, and formatting engine. Constrain it to the civic, proprietary, or API-derived data supplied in the workflow.
Human oversight remains non-negotiable. AI agents should handle research, formatting, API aggregation, and repetitive checks. Strategic direction, template design, brand safety, and randomized quality assurance should still be owned by experienced operators.
Advanced Execution: Implementing the Model Context Protocol
As automation matures, technical SEO workflows are moving beyond visual node builders. Model Context Protocol represents a shift in how AI systems interact with external tools, file systems, and databases.
Deconstructing the Model Context Protocol Architecture
Model Context Protocol is an open standard designed to let AI assistants securely connect to tools, applications, and data repositories.
Traditional automation platforms require developers to manually map variables and configure logic. MCP exposes approved tools directly to an AI interface through local or remote servers. The AI can then execute complex, multi-step actions through natural language while staying inside controlled tool boundaries.
For programmatic SEO, this matters because the AI can work with live context:
- Search Console data.
- Google Analytics 4 data.
- Supabase or PostgreSQL databases.
- GitHub repositories.
- Keyword datasets.
- Internal editorial guidelines.
- Crawl and indexation exports.

Strategic Applications of MCP in Technical SEO Automation
Custom MCP connectors can accelerate programmatic analysis, content generation, and auditing.
Key use cases include:
- Autonomous competitive gap analysis: An MCP server connected to SEO data providers can let an analyst ask the AI to identify top competitors, keyword overlap, backlink gaps, and semantic deficiencies.
- Performance monitoring and decay detection: An MCP connector for Google Search Console can help diagnose programmatic pages with impression drops, find pages sitting in positions 8 through 15, and suggest improvements to answer sections or heading structure.
- Technical SEO audits at programmatic scale: Large batches of generated URLs can be checked for indexing status, crawl errors, rendering problems, or schema gaps.
- Database integration for safer content generation: An AI agent connected to Supabase can check existing focus keywords, prevent cannibalization, read editorial rules, and generate compliant drafts based on approved data.
| MCP Server Connector | Core SEO Automation Capability |
|---|---|
| Google Search Console connector | Extracts bulk indexing status, identifies ranking decay, and analyzes query performance for pages in positions 8-15. |
| Google Analytics 4 connector | Pulls traffic, engagement, and session data to measure programmatic page ROI. |
| Supabase or PostgreSQL connector | Queries existing URLs and focus keywords to reduce index bloat and cannibalization. |
| GitHub or Git connector | Pushes generated pages to the repository and triggers deployment. |
| Google Ads or Meta Ads connector | Pulls CPC and conversion data to calculate the commercial viability of new page clusters. |
The strategic deployment of MCP servers transforms an AI assistant from a passive chat interface into an active technical operator. Organizations that need to connect AI systems to protected data often need Model Context Protocol integration for OAuth, token management, permission boundaries, and production deployment.
Structuring Output for Machines and Human Users
Even when the data source is strong and the automation is intelligent, the final rendering of the page determines whether search engines and AI systems can understand it.
Plain HTML Delivery and Crawler Accessibility
Primary text should be immediately available in plain HTML. Essential information, factual claims, and local data should not be hidden inside JavaScript-only accordions, tabs, sliders, or client-rendered components that require interaction before the content exists in the DOM.
For programmatic SEO, the architecture should prioritize static site generation or server-side rendering. The initial HTML delivered to the crawler should contain the primary content, local context, target entities, FAQs, schema, and conversion path.
This is one reason Astro can be a strong fit for SEO-focused sites: content can be rendered as static HTML while still allowing interactive islands where they make sense.
Synthesizing Schema Markup and Structured Data
Schema markup is a direct communication layer between a programmatic website and machine systems. It defines entity relationships, authorship, content boundaries, and page purpose.
Important schema types include:
- Organization and Person schema: Map the brand and author entities, supporting E-E-A-T signals.
- FAQPage schema: Helps AI and search extract discrete question-and-answer blocks.
- Article and WebPage schema: Define the page’s role in the site architecture.
- ImageObject and VideoObject schema: Add context, captions, alt text, and licensing information for media assets.
- LocalBusiness schema: Useful when programmatic pages support location-specific service discovery.
Schema should not compensate for weak visible content. It should clarify strong content that users can already read.
The Emergence and Implementation of llms.txt
As AI ingestion protocols evolve, sites are beginning to use llms.txt at the domain root. Similar in placement to robots.txt, an llms.txt file is usually written in Markdown and gives AI models a concise map of the site’s factual scope, canonical documentation links, entity definitions, and high-value resources.
For a programmatic SEO site, llms.txt can help explain:
- The site’s core services and expertise.
- Canonical service and location URLs.
- Important documentation or case study pages.
- Preferred citations and source pages.
- Pages that summarize the business entity and author.
It is not a replacement for crawlable HTML, schema, or internal links. It is an additional machine-readable guide that can support AI discovery.
Common Operational Mistakes and Strategic Considerations
Programmatic SEO introduces risk when deployed without governance. The largest problems are rarely caused by automation itself. They come from weak data, weak thresholds, weak review, and weak architecture.
Index Bloat and Crawl Budget Exhaustion
Generating thousands of URLs without enough differentiating data creates index bloat. Search engines can identify the domain as a source of low-value duplication and reduce crawl attention across the site.
Programmatic generation should be governed by intent mapping and strict data validation thresholds. If a page does not have enough unique data to deserve indexing, it should not be published as an indexable URL.
Semantic Keyword Cannibalization
Without a central database tracking focus keywords, URL intent, and existing content coverage, automated workflows can generate overlapping pages. Those pages compete with each other in search results and dilute authority.
Every programmatic system should maintain a source of truth for:
- Primary query intent.
- URL slug.
- Canonical page owner.
- Related services.
- Related locations.
- Published date.
- Last refreshed date.
- Indexation status.
Algorithmic Hallucinations and Data Integrity
LLMs should not generate factual assertions without a constraining data feed. A model asked to “write a local SEO page for Miami construction permits” may invent claims unless it is grounded in real permit data.
The safer architecture is retrieval-first:
- Fetch the source data.
- Normalize the fields.
- Calculate the factual outputs.
- Pass only those facts to the model.
- Ask the model to synthesize, format, and explain.
- Validate the result against the source data.
Neglecting Human-in-the-Loop Oversight
Complete autonomy is a dangerous assumption in enterprise SEO. AI agents and workflows should act as force multipliers for data research, HTML formatting, API aggregation, and quality checks.
Template architecture, brand positioning, legal sensitivity, final approval rules, and random quality audits should remain under human control.
Decision Matrix: When to Build, Automate, or Optimize
Business leaders should evaluate digital maturity, existing infrastructure, and data assets before investing in advanced programmatic SEO.
When to Build
If the organization lacks a robust digital foundation, prioritize the website architecture first. Startups and local businesses need fast, secure, crawlable infrastructure before they attempt programmatic scale.
For this phase, the priority is full-stack development, CMS decisions, static or server-rendered architecture, clean information architecture, and conversion paths.
When to Automate
If the organization already has unique datasets and a functional website, the focus can shift to scaling. Examples include proprietary real estate listings, CRM analytics, service logs, keyword inventories, or location-specific operational data.
This is where n8n workflows, AI agents, API integrations, and MCP systems can reduce customer acquisition cost by capturing long-tail intent without building a large manual content operation.
When to Optimize
If an existing programmatic deployment or large content library is losing traffic after algorithm updates or AI Overview changes, the strategy should pivot to technical SEO audits and GEO.
That means schema restructuring, entity clarification, content pruning, noindex decisions, crawl diagnostics, internal linking repair, and integration of performance data from Search Console or analytics tools.
| Organizational Status | Primary Objective | Recommended Strategic Action |
|---|---|---|
| Legacy site, slow load times, poor foundational HTML | Establish a secure, crawlable baseline | Build: focus on full-stack development and CMS migration. |
| Functional site, access to proprietary or local data, high manual content costs | Scale organic reach and reduce customer acquisition cost | Automate: deploy n8n workflows, APIs, and AI agents. |
| Large content library, dropping traffic, losing visibility to AI Overviews | Reclaim lost traffic and adapt to generative search engines | Optimize: implement GEO, schema markup, and llms.txt. |
Frequently Asked Questions
Is AI-generated content automatically penalized by Google?
Current search algorithms and guidelines do not inherently ban or penalize AI-generated content. Instead, algorithms penalize content that demonstrates a lack of originality, expertise, and added value to the user.
If artificial intelligence is used to format, structure, and synthesize unique datasets into a useful and readable format, the output can align with people-first content objectives.
What is the fundamental difference between SEO and GEO?
Traditional Search Engine Optimization focuses on optimizing digital assets to rank higher in organic listings through crawlability, relevance, internal links, backlinks, and authority.
Generative Engine Optimization is the modern discipline of structuring and formatting content so AI answer engines, such as ChatGPT, Perplexity, and Google AI Overviews, can extract, trust, and cite the information in summarized responses.
How does the Model Context Protocol differ from tools like Zapier or n8n?
Traditional automation platforms require developers to manually map variables and connect visual logic nodes to create structured automations.
Model Context Protocol provides a standardized connection layer that allows an AI model to interface with an API, database, repository, or external tool through approved server capabilities. This lets the AI plan and execute multi-step actions through natural language while staying within defined permission boundaries.
How do technical architects prevent thin content penalties in a programmatic SEO campaign?
Thin content is avoided by injecting unique, verifiable data into every programmatic URL.
That can include municipal open data APIs, proprietary CRM data, verified local reviews, historical service records, geospatial context, pricing calculations, and freshness loops that update the page as the underlying data changes.
What exactly is a freshness loop in programmatic SEO?
A freshness loop is an automated technical process that continuously checks internal or external data sources for updates.
When new data is detected, the workflow recalculates page statistics, updates relevant templates or content modules, validates the result, and pushes the changes live. This keeps the content current, factually accurate, and more useful for crawlers and users.
Conclusion and Strategic Next Steps
The era of scaling organic traffic by mass-publishing generic, templated programmatic pages has closed. AI Overviews, answer engines, and Generative Engine Optimization demand a more sophisticated approach to digital growth.
Sustained success requires unique datasets, complex automation workflows, tools like n8n and Model Context Protocol, and rigorous technical SEO and structured data standards.
Executing this architecture is not only a marketing effort. It is a software engineering and data orchestration effort. Businesses that transform static websites into structured, authoritative, dynamically updated data hubs can earn a stronger share of visibility in the AI search ecosystem. Organizations that rely on outdated keyword swapping and low-effort text generation will become easier for algorithms to ignore.
Building, scaling, and maintaining these systems requires a multidisciplinary approach across digital strategy, software development, data analysis, and AI implementation.
Schedule a discovery call to explore how custom AI automation and advanced technical SEO can support sustainable, scalable growth for your organization’s digital infrastructure.
Works Cited
- Google Search’s guidance on using generative AI content on your website
- Google AI Search Guidelines (2025): What They Mean for SEO
- Google AI Overviews: What’s Changing for SEO & SEA in 2025
- Generative engine optimization (GEO): How to win AI mentions
- Programmatic SEO: Build High-Intent Pages Without Thin Content
- Generative Engine Optimization (GEO) in 2025: Get Cited by AI
- 10-step framework for generative engine optimization
- I built a full SEO automation pipeline in n8n that updates my website daily
- City of Miami Developer Portal
- City of Orlando Open Data Portal
- Data Explorer - City of Miami
- The Complete Guide to SEO Automation with n8n Using AI Agents
- How I used n8n for programmatic SEO
- Claude MCPs and Prompts for SEO Blog Automation
- AI-powered product research and SEO content automation
- AI agents in SEO: A practical workflow walkthrough
- AI Search Content Optimization: The Complete Guide
- GEO: The Complete Guide to AI-First Content Optimization 2025
- SEO Automations are 10X Easier With Claude MCP
- What is Model Context Protocol?
- Seamless Frase Integration with Claude Code, Cursor, and More
- Top SEO MCP Servers in 2026: Tools and Use Cases
- Claude MCP Connector Guide: Setup, Auth and Top Use Cases 2026
- Google Search’s guidance about AI-generated content